RS9 Everyday Agent Bench
Best results
Score out of 100, highest first
Best value
Cost per task passed, cheapest first
Subscription agents: what the same work would cost at public API prices. OpenRouter: the real charge.
20 tasks · one attempt each
rs9.com.au/benchmarks
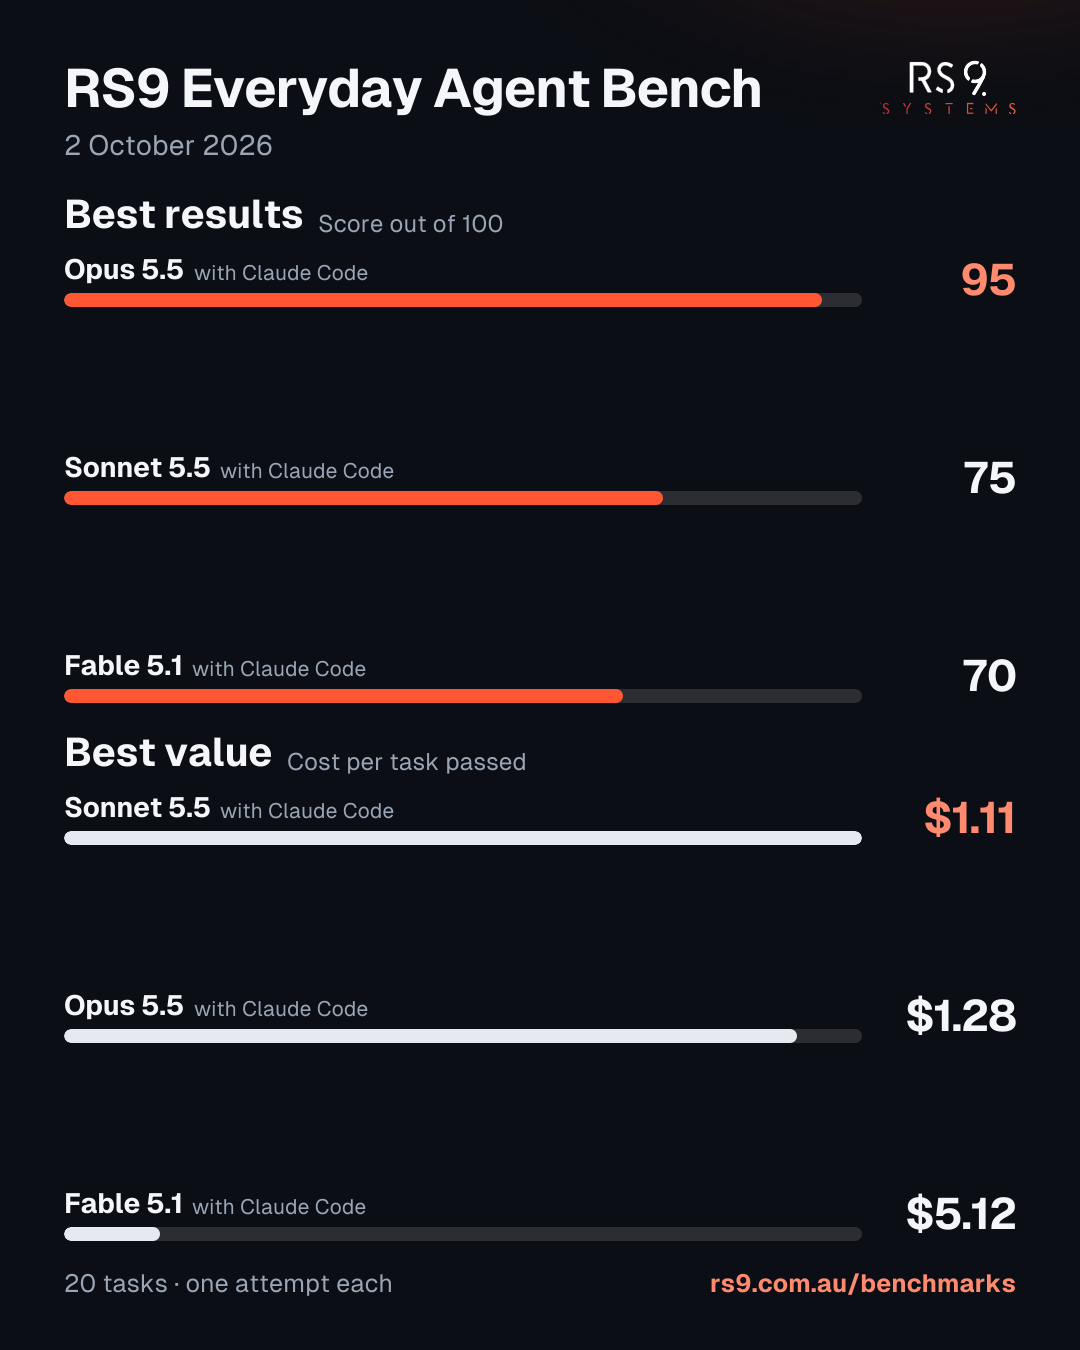
Score is the percentage of tasks passed, one attempt each. Partial credit (in the table below) gives each task the share of its checks that passed, so it can split agents on the same score.
Value is total cost divided by tasks passed, so an agent that's cheap but fails a lot doesn't look good. It sits beside the score and never changes it.
A few of the 20 tasks are “frontier” tasks, added to stretch the top models.
View the results as a table
| Model | Agent tool | Score | Tasks passed | Partial credit | Total time |
|---|---|---|---|---|---|
| Opus 5.5 | Claude Code | 95 | 19 of 20 | 99 | 1 h 48 min |
| Sonnet 5.5 | Claude Code | 75 | 15 of 20 | 99 | 1 h 36 min |
| Fable 5.1 | Claude Code | 70 | 14 of 20 | 99 | 2 h 42 min |
View the value board as a table
| Model | Agent tool | Cost per task passed | Tasks passed |
|---|---|---|---|
| Sonnet 5.5 | Claude Code | $1.11 per task passed | 15 of 20 |
| Opus 5.5 | Claude Code | $1.28 per task passed | 19 of 20 |
| Fable 5.1 | Claude Code | $5.12 per task passed | 14 of 20 |
We gave 3 coding agents the same 20 tasks from the kind of work RS9 does, then checked whether each one got the job done. One attempt each, same brief and files, 60 minutes a task.
It's not a research study. Each agent gets one go at each task, so a gap of a task or two means very little. And these are our tasks, so how an agent does here says little about how it'll do on yours. How it's scored, and where it falls short, is on the methodology page.
Latest run: . These are the versions we tested that day. Update an agent and its numbers can change.
Over time
Is each agent holding steady?
Score, run by run
We rerun the benchmark regularly. Each line follows one agent across the dated runs. With one attempt per task, a few points either way is normal wobble. A steady drift is what to look for.
Select an agent in the key to pick out its line.
A diamond means the agent's model or client version changed since its last run. Select an agent to step through its points with the keyboard.
View this chart as a table
| Model and agent tool | 30 Sept | 2 Oct |
|---|---|---|
| Fable 5.1 with Claude Code | score 70, $5.91 per pass | score 70, $5.12 per pass |
| Opus 5.5 with Claude Code | score 95, $1.62 per pass | score 95, $1.28 per pass |
| Sonnet 5.5 with Claude Code | score 85, $1.00 per pass | score 75, $1.11 per pass |
| GPT-6 Astra with Codex | score 85, $1.75 per pass | not run |
| Sol 6.1 with Codex | score 80, $0.45 per pass | not run |
| Grok 4.7 with Grok Build | score 65, $4.56 per pass | not run |
| Muse Spark 1.3 with Muse Code | score 55, cost n/a | not run |
| DeepSeek V4.1 Flash with OpenCode (OpenRouter) | score 70, $0.085 per pass | not run |
Task by task
Every result
- Pass
- Fail
- Timed out
- Error
- Skipped
| Task | Fable 5.1with Claude Code | Opus 5.5with Claude Code | Sonnet 5.5with Claude Code |
|---|---|---|---|
| Software | |||
| Codebase-wide changeFrontier | FailTime 10:43 | PassTime 9:09 | PassTime 6:33 |
| Checkout bug fixing | PassTime 8:58 | PassTime 4:45 | PassTime 4:15 |
| Database migration | PassTime 7:39 | PassTime 6:09 | PassTime 4:40 |
| Research and decisions | |||
| Fact-check product claims | PassTime 2:51 | PassTime 1:10 | PassTime 0:39 |
| Grant eligibility research | PassTime 5:28 | PassTime 2:25 | FailTime 1:10 |
| Documents | |||
| Contract revisions | PassTime 4:20 | PassTime 2:32 | PassTime 2:08 |
| Tender response | PassTime 6:03 | PassTime 3:44 | PassTime 2:06 |
| Tender pricingFrontier | FailTime 7:49 | PassTime 4:28 | PassTime 4:06 |
| Data | |||
| A/B test analysis | PassTime 2:32 | PassTime 1:39 | PassTime 0:59 |
| Month-end reconciliation | PassTime 3:17 | PassTime 2:45 | PassTime 2:08 |
| Interfaces and technical work | |||
| Small web shopFrontier | FailTime 13:57 | PassTime 10:32 | FailTime 12:35 |
| Fabrication cut list | PassTime 1:37 | PassTime 0:58 | PassTime 5:21 |
| Quote form with pricing rules | FailTime 10:15 | PassTime 15:29 | FailTime 5:08 |
| Picking up where someone left off | |||
| Pick up someone else's half-finished feature | PassTime 5:21 | PassTime 3:50 | PassTime 2:13 |
| Incident investigation | PassTime 6:06 | PassTime 3:02 | PassTime 2:28 |
| CAD and fabrication | |||
| Electronics enclosure (3D CAD) | PassTime 5:34 | PassTime 4:12 | PassTime 1:30 |
| Sheet-metal part (2D CAD) | FailTime 1:59 | PassTime 1:14 | FailTime 0:42 |
| Multi-part CAD assemblyFrontier | PassTime 19:47 | PassTime 12:24 | PassTime 14:16 |
| Front-end design | |||
| Page design from a reference | PassTime 8:11 | PassTime 4:46 | FailTime 2:24 |
| Build a page from a mockup | FailTime 29:42 | FailTime 12:54 | PassTime 21:02 |
Speed
Passing versus time taken
Score against time taken
Each dot is one model with its agent tool. Higher is a better score. Further left means less total time across its 20 attempts. Top left is the best spot. Hover or tab to a dot to see which is which.
Times include the provider's server speed and queueing, so a slow time can mean a busy server.
View this chart as a table
| Model | Agent tool | Score | Tasks passed | Total time |
|---|---|---|---|---|
| Opus 5.5 | Claude Code | 95 | 19 of 20 | 1 h 48 min |
| Sonnet 5.5 | Claude Code | 75 | 15 of 20 | 1 h 36 min |
| Fable 5.1 | Claude Code | 70 | 14 of 20 | 2 h 42 min |
Cost
What each passed task cost
Subscription agents don't bill per task. So we count the tokens each attempt used and price them at the provider's public API rates. It's not what anyone paid, but it puts every agent on one scale.
The OpenRouter model shows the real charge, which can sit well below list price if the host discounts it. If there's no public price for a model, it says “price unknown”. Never $0.
Cost per task passed
Total cost divided by tasks passed, for each agent. A shorter bar is cheaper. All amounts are US dollars.
View this chart as a table
| Model | Agent tool | Cost per pass | Total cost | Tasks passed | Basis |
|---|---|---|---|---|---|
| Sonnet 5.5 | Claude Code | $1.11 | $16.63 | 15 of 20 | Subscription: what the same tokens would cost at the provider's public API price |
| Opus 5.5 | Claude Code | $1.28 | $24.25 | 19 of 20 | Subscription: what the same tokens would cost at the provider's public API price |
| Fable 5.1 | Claude Code | $5.12 | $71.66 | 14 of 20 | Subscription: what the same tokens would cost at the provider's public API price |
Score against cost per task passed
Each dot is one model with its agent tool. Higher is a better score. Further left means each passed task cost less. Top left is the best spot. Hover or tab to a dot to see which is which.
View this chart as a table
| Model | Agent tool | Score | Tasks passed | Cost per pass |
|---|---|---|---|---|
| Opus 5.5 | Claude Code | 95 | 19 of 20 | $1.28 |
| Sonnet 5.5 | Claude Code | 75 | 15 of 20 | $1.11 |
| Fable 5.1 | Claude Code | 70 | 14 of 20 | $5.12 |
The agents
What we tested
Times include the provider's server speed and queueing, so a slow time can mean a busy server.
Fable 5.1
with Claude Code
- Model
- Claude Fable 5.1
- Reasoning
- High
- Client version
- 2.1.285 (Claude Code)
- Score
- 70 · partial credit 99
- Passed
- 14 of 20
- Total time
- 2 h 42 min
- Total cost
- US$71.66
- Cost per pass
- US$5.12
Subscription, at API list price.
Claude Code in headless mode, high reasoning effort, on a Claude subscription.
Opus 5.5
with Claude Code
- Model
- Claude Opus 5.5
- Reasoning
- High
- Client version
- 2.1.285 (Claude Code)
- Score
- 95 · partial credit 99
- Passed
- 19 of 20
- Total time
- 1 h 48 min
- Total cost
- US$24.25
- Cost per pass
- US$1.28
Subscription, at API list price.
Claude Code in headless mode, high reasoning effort, on a Claude subscription.
Sonnet 5.5
with Claude Code
- Model
- Claude Sonnet 5.5
- Reasoning
- High
- Client version
- 2.1.285 (Claude Code)
- Score
- 75 · partial credit 99
- Passed
- 15 of 20
- Total time
- 1 h 36 min
- Total cost
- US$16.63
- Cost per pass
- US$1.11
Subscription, at API list price.
Claude Code in headless mode, high reasoning effort, on a Claude subscription.
Results file
Downloads
History
Runs
- 2 October 2026 · this page
- 30 September 2026